Credit scoring: ensemble online tree architectures for real-time conversion optimization
A bank or a sales desk has thousands of potential customers to contact but limited time to make the calls. This tool learns one completed interaction at a time to estimate who is likely to subscribe to a product, combining random structural partitioning with adaptive loss-driven trees to generate an analytical ranking that prioritizes high-probability clients in real time.
The scene
When an institutional banking desk or marketing division executes large-scale customer engagement campaigns, outbound resource allocation faces severe operational bottlenecks. Processing a high-volume client directory indiscriminately generates large overhead, inflates customer fatigue, and yields low conversion rates, while missing critical lead windows.
To maximize customer lifetime value and optimize outbound conversion funnels, engagement strategies must utilize real-time analytical ranking engines.
To benchmark this capability on historical data, the dual-tree streaming pipeline was run on 45,211 telemarketing interactions from the industry-standard UCI Bank Marketing dataset. In the test stream, 1,048 of 9,043 calls (11.6%) end in a subscription. The model operates within a strict predictive framework, learning incrementally from each finalized customer interaction to dynamically score and rank subsequent leads as soon as they interface with the system.
Core Capabilities
| Tool | Strategic Function | Operational Impact |
|---|---|---|
| MondrianForest | Online structural partitioning | Segments the multi-dimensional customer attribute space using stochastic geometric partitions, providing immediate probability scores for incoming profiles. |
| SGTClassifier | Loss-driven adaptive tracking | Utilizes regularized second-order Taylor expansions to optimize decision splits, delivering an independent evaluation layer. |
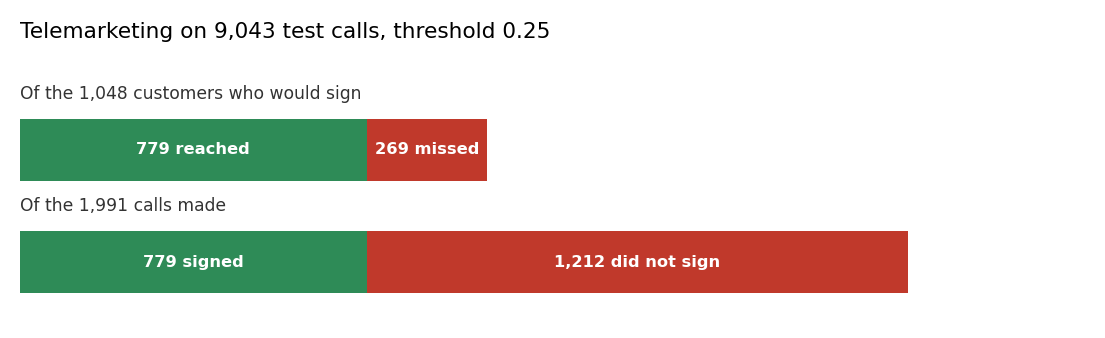
Green: right. Red: wrong. Top bar: what happened to the 1,048 customers who would sign. Bottom bar: what the 1,991 calls produced.
1. Stochastic spatial feature partitioning (MondrianForest)
Traditional ensemble random forests demand complete batch recalculations of structural cuts when data properties drift over time. The integrated Mondrian forest architecture bypasses this limitation by treating spatial partitions as independent stochastic processes. Client attribute vectors—including age, financial balances, historical campaign outcomes, and engagement metrics—are mapped into multidimensional blocks. This allows the model to compute localized density estimates continuously and adjust conversion probabilities without global structural degradation.
2. Loss-driven mathematical split optimization (SGTClassifier)
Operating as the analytical reference layer of the pipeline, the Stochastic Gradient Tree classifier guides structural splits through localized optimization dynamics. Instead of relying on random feature selection, the tree chooses division boundaries by evaluating the Newton step of the empirical loss function. A localized t-test verifies the statistical significance of each proposed partition before execution. This process ensures stable, noise-resilient structural updates on continuous transaction streams.
Execution Workflow
For every newly processed customer profile or live communication event, the streaming conversion pipeline executes a three-stage validation protocol:
- Parallel Feature Ingestion: The client attribute vector is fed simultaneously to both streaming tree layers.
- Dual-Model Scoring Consensus: MondrianForest evaluates spatial density to assess profile affinity, while SGTClassifier outputs an independent score driven by loss optimization.
- Calibrated Threshold Enforcement: The final conversion probability is computed as the arithmetic mean of both metrics. Profiles exceeding the customized 0.25 operational threshold are routed to active engagement queues.
Empirical Performance
The processing pipeline was verified using a chronological data split consisting of a 36,168-sample training stream and a 9,043-sample active test stream containing 1,048 verified conversions.
| Metric | Value |
|---|---|
| ROC-AUC, MondrianForest | 0.859 |
| ROC-AUC, SGT | 0.833 |
| ROC-AUC, ensemble | 0.875 |
| Threshold | 0.25 |
| Calls made (out of 9,043) | 1,991 |
| True positives | 779 |
| False positives | 1,212 |
| Missed (signed but not called) | 269 |
| Recall | 74.3% |
| Precision | 39.1% |
| F1 | 51.3% |
| Training time (Kaggle CPU) | 166 s |
Strategic Decision Threshold Optimization
Traditional model deployments rely mechanically on a generic 0.5 classification cutoff. On this dataset, a 0.5 threshold reaches only 19% of the customers who would sign (198 out of 1,048): the other 81% are never called.
Calibrating the operational threshold down to 0.25 pushes the Recall rate to 74.3% with a Precision of 39.1%. Roughly two out of every five calls end in a signature: 779 of the 1,048 customers who would sign are reached with 1,991 calls.
Target Enterprise Use Cases
This streaming predictive architecture is optimized for retail banking and enterprise sales desks:
- Live Outbound Campaign Optimization: Ranks the customers to call next, so a sales desk spends its calls on the profiles most likely to sign.
- Scoring a profile before the call: Each customer gets a score from the two trees before anyone dials.
- Dynamic Product Adherence Tracking: Keeps learning from each completed call, with no scheduled batch retraining.
Details
Implementation
The pipeline is in pipelines/finance/credit_scoring.py.
Primitives chained, each with its own page:
References
- Lakshminarayanan, B., Roy, D. M., Teh, Y. W. (2014). Mondrian Forests: Efficient Online Random Forests. NeurIPS.
- Gouk, H., Pfahringer, B., Frank, E. (2019). Stochastic Gradient Trees. ACML.
- Dataset: UCI Bank Marketing, bank-full.csv. 45,211 rows, 16 features, target y. Original source: S. Moro, P. Cortez, P. Rita, A Data-Driven Approach to Predict the Success of Bank Telemarketing.
These pages describe measurements on historical data. Not a forecast, not financial advice.